Configure AI providers
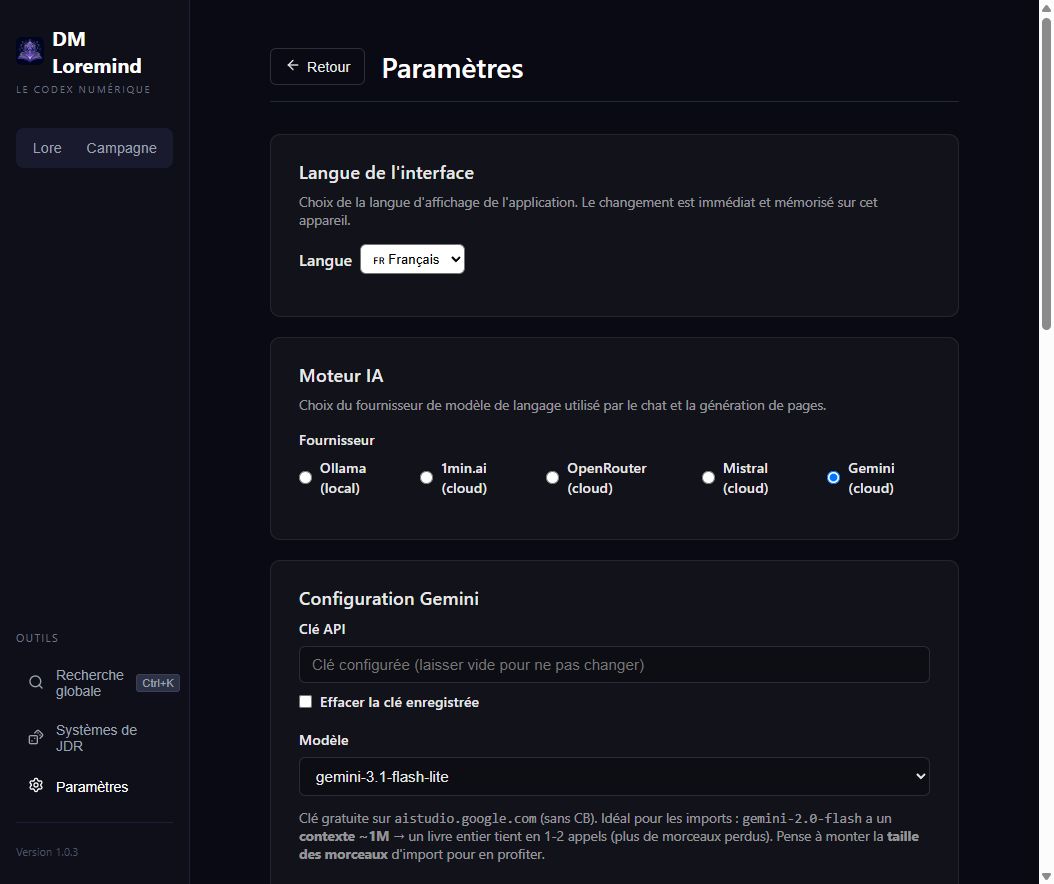
Open Settings → AI engine. One conversation provider is active at a time for chat, generation and PDF analysis. Workshop embeddings are configured separately.
Common setup
- Select the provider.
- Configure its connection: an Ollama URL or a cloud API key.
- Choose a model from its catalogue.
- Click Save.
- Return to a sheet and try a short question in AI Assistant.
Saved keys are not displayed again. A blank key field preserves an existing key; use Clear saved key to remove it.
Ollama
Ollama must be installed and reachable from Brain. Download a conversation model, then select it in Settings. The model manager can also start downloads from the application.
| Installation | Usual address from Brain |
|---|---|
| Desktop, Ollama on the same PC | http://localhost:11434 |
| Compose-managed Ollama | http://ollama:11434 |
| Host Ollama with Docker deployment | http://host.docker.internal:11434 |
The context window controls how much text the model can consider. Increasing it uses more memory; reduce import chunks or history if the machine cannot keep up. See Troubleshooting.
Cloud providers
| Provider | Loremind configuration |
|---|---|
| 1min.ai | 1min.ai API key and a model from the provider-grouped list |
| OpenRouter | OpenRouter API key and model; a free-model filter is available |
| Mistral | Mistral API key and conversation model |
| Gemini | Google AI Studio API key and Gemini conversation model |
Obtain the key from your account with the corresponding provider. Catalogue, quotas, pricing and model access depend on that account. A “free” label or valid key does not guarantee unlimited capacity. Also check that the selected model produces text: catalogues may expose specialised image, audio or embedding models.
Cloud providers receive requests and context relevant to the feature. See Data and sharing.
Choose a model for your workflow
Try a short request first, then a representative task: narrative text, a structured sheet or an import. For imports, check context capacity, structured output quality and response time. Adjust chunks and timeout to the model's limits, then review suggestions. Prefer the catalogue available in your installation over an old example model name.